刘芷溢
最近更新
FlashAttention v1-v4:从 IO 感知到异步流水与硬件协同
沿着 FlashAttention v1-v4 的论文、作者博客与源码,拆解 Ampere、Hopper、Blackwell 如何改变 attention 的数据路径、线程分工和瓶颈,并用调度图解释 copy、MMA、softmax 与输出校正如何真正重叠。
理解 H100:从硬件数据路径到 Nsight Compute 瓶颈分析
沿着 kernel 的分配、指令发射、访存与异步矩阵计算,建立 H100 的硬件工作模型,并把 Nsight Compute 的吞吐、调度、事务和依赖指标组织成可验证的瓶颈诊断方法。
Bridging the Gap Between Promise and Performance for Microscaling FP4 Quantization 论文笔记
以格式、量化算法和 GPU Kernel 的跨层约束为主线,拆解 ICLR 2026 论文 Bridging the Gap Between Promise and Performance for Microscaling FP4 Quantization,解释旋转为何改善 MXFP4 却可能伤害 NVFP4、MR-GPTQ 如何修正这一矛盾,以及 QuTLASS 的真实收益与部署边界。
FP4、FP8 与 INT8/INT4:数值范围、块缩放与推理计算精度
从标量编码、共享 scale 与有效位宽出发,拆解 INT8、FP8、MXFP8、INT4、MXFP4、NVFP4 的表示范围,并沿 GEMM、GQA/MLA Attention 数据流解释 8 bit/4 bit 推理真正使用的乘法、累加、Softmax 与输出精度。
从 EAGLE 到 DFlash 2:SGLang 与 SpecForge 的投机解码训练和推理
沿 EAGLE、EAGLE-2、EAGLE-3、DFlash、DSpark 和 DFlash 2 的演进,解释 draft 的训练目标、数据对齐、推理状态与验证预算,并对照 SpecForge 训练和 SGLang serving 源码串起完整流程。
README
CuTe FlashAttention-2 case-study benchmark This directory preserves the exact teaching kernel, benchmark harness, raw results, and figure generator used by the corresponding tom-jerr blog post.
CuTe 详解:以 FlashAttention-2 拆解 Layout、TiledCopy 与 TiledMMA
以一份可运行的 FlashAttention-2 前向 Kernel 为贯穿案例,从坐标函数和线程所有权出发,详解 CuTe 的 Layout algebra、Tensor、TiledCopy、TiledMMA、寄存器重解释与流水线,并用正确性和性能实验检查这些抽象最终生成了什么。
LLM 量化综述:数据格式、PTQ 与 QAT 的算法演进
从 INT8、FP8、INT4、MXFP4、NVFP4 的表示范围与舍入误差出发,按 8 bit、4 bit 和低于 4 bit 梳理 PTQ/QAT,解释各方法解决的问题、相对前作的创新、核心优化与数值稳定性,并对应到 llm-compressor 的工程实现。

paper-notes
21 篇文章
active slam
Active Slam Overview Active Slam 的工作流程: Perception: 传感器数据获取与预处理 SLAM(Localization + Mapping + Loop Closure) Candidate Generation: 生成候选观测点(frontiers/viewpoints) Evaluator: 对每个候选估算:预期信息增益(raycast / mutual information / belief propagation)、执行代价(路径长度、能耗)、定位风险(协方差增长)、碰撞风险。 Planner: 短期执行目标或控制序列(通常只执行第一步或首...
Prepacking
Prepacking: A Simple Method for Fast Prefilling and Increased Throughput in Large Language Models 阅读笔记.
deepseekv4
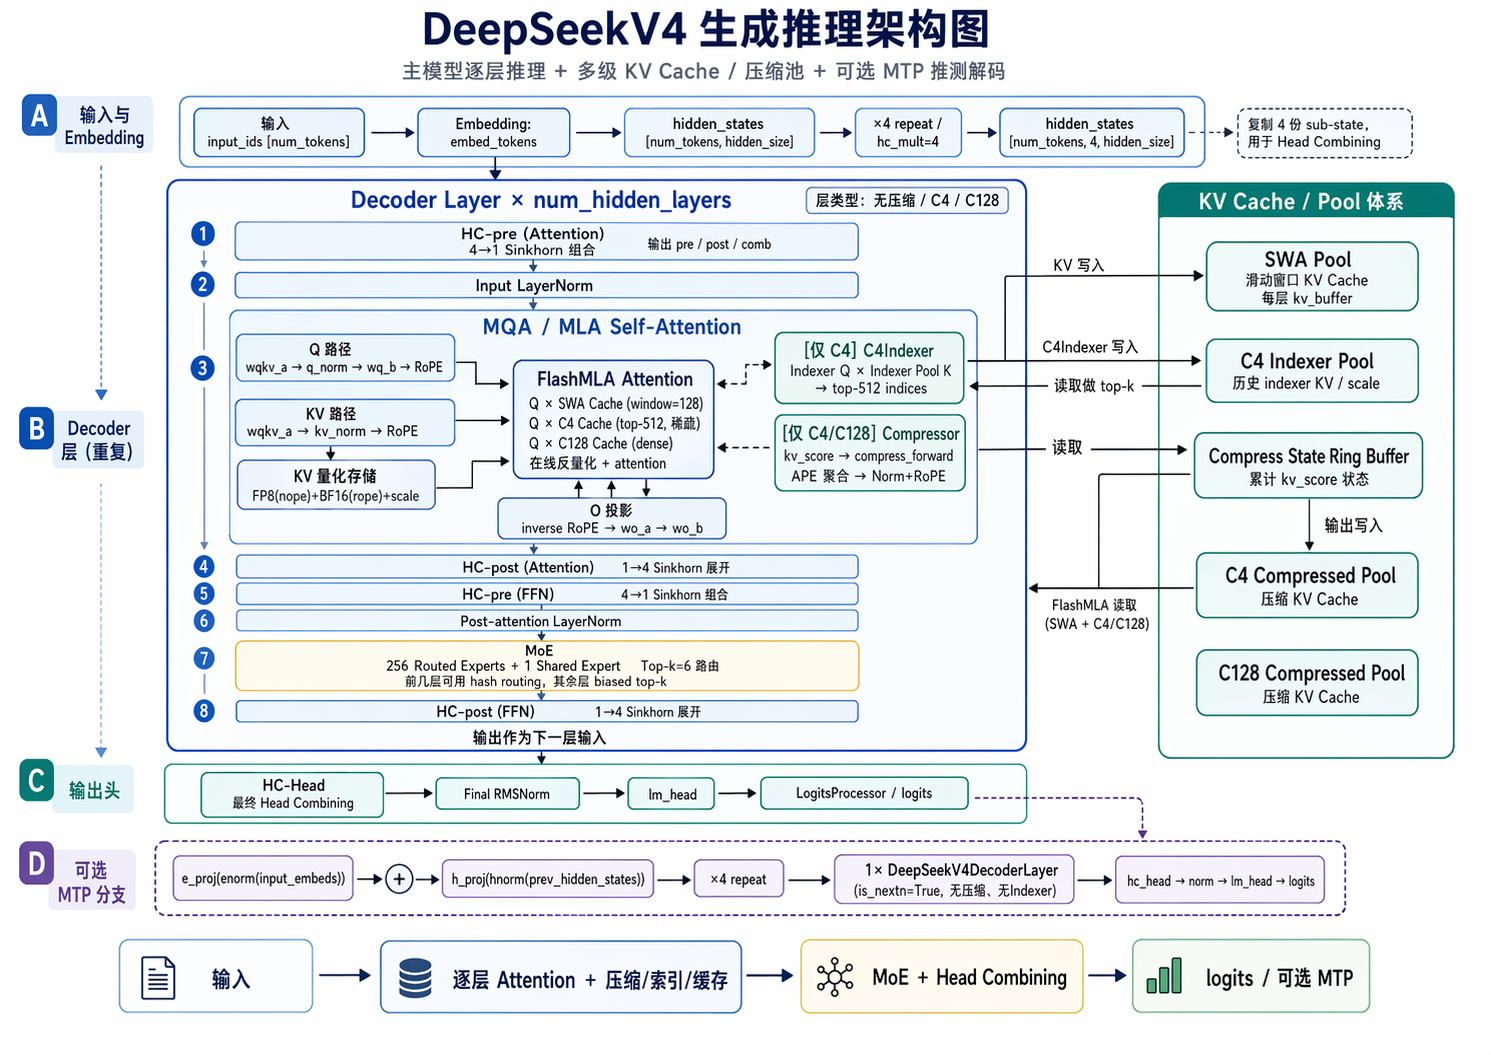
DeepseekV4 模型架构 Attention 这里所有的 Attention 实际上都是 MLA 的方式计算,只是 KV 的压缩程度不同以及是否有 DSA 参与 CSA(Compressed Sparse Attention) Compressed KV Entries:每 m 个 token 生成 1 个压缩 KV,但这个压缩 KV 实际会参考当前 block 的 m 个 token,以及前一个 block 的 m 个 token,一共 2m 个候选 token,然后用 learned softmax 权重加权求和(Overlap) DSA Strategy:对于每个 query,选择...
Chunked Prefill
Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve Motivation Prefill 因为是长序列计算有高延迟,decode 是低延迟但是 GPU 利用率很低 现有的 batching 调度交错 prefill batch 和 decode batch,让高吞吐和低延迟变得困难 Batch 对 decode 吞吐量提升很大,对 prefill 影响小 Decode 阶段计算资源未被充分利用 SM 计算资源空闲:可以在解码批次中处理更多令牌,而不会显着增加其延迟。 线性层在预填充和解码阶段占据了大部分运...
PageAttention
Efficient Memory Management for Large Language Model Serving with PagedAttention Motivation 当时的大模型推理系统直接通过 pytorch 为每个 req 预分配一块连续的内存,会造成内部碎片(因为分配的会过多),外部碎片(因为需要分配连续的);让整个系统的吞吐量骤降,无法高效利用和复用显存 Key Observation KV Cache 当模型生成新的 token 时,它会随着时间动态增长和收缩,并且它的生命周期和长度是未知的。 现有系统预分配 max_token 长度的显存,会导致内部碎片。因为实际...
SGLang
SGLang: Efficient Execution of Structured Language Model Programs.
distserve
DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving Motivation 现有的 LLM 服务系统将 prefill 和 decode 两个阶段并置,并批量计算所有用户和请求的预填充和解码。我们发现这种策略不仅会导致强烈的预填充解码干扰,而且还会耦合两个阶段的资源分配和并行计划。 prefill 关注 TTFT decode 关注 TPOT 现有系统为了满足两种不同的延迟,过度配置计算资源或者牺牲其中一个来满足另一个;这会造成成本效益不足 因此,优化每...
DFLASH
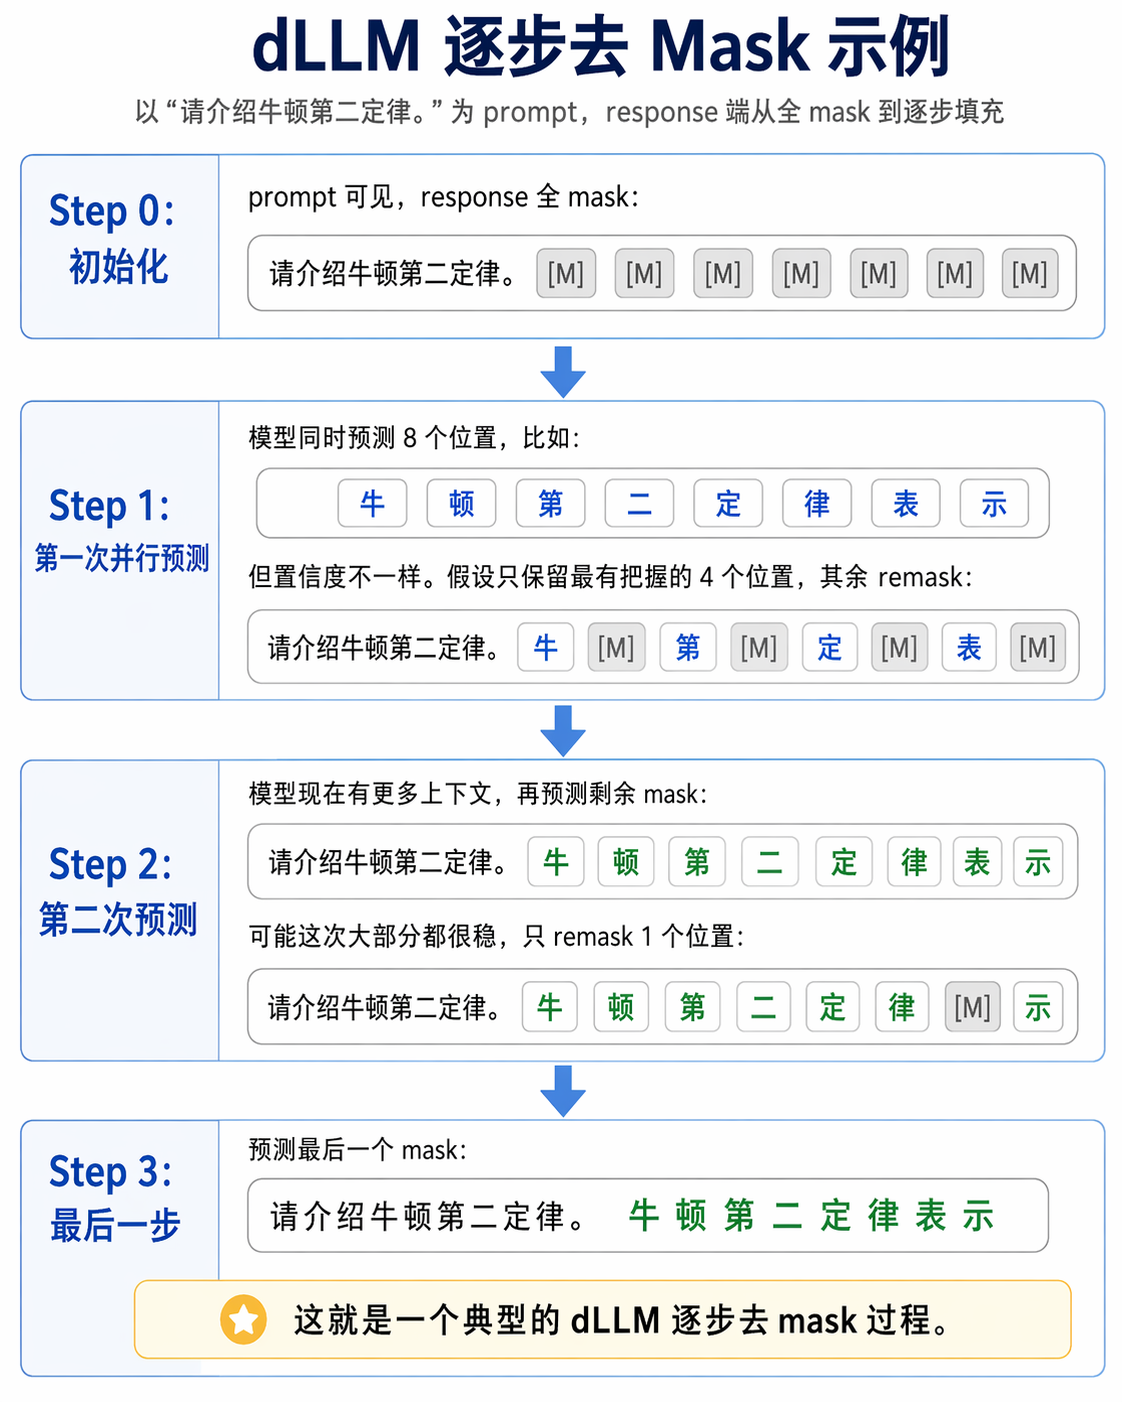
DFlash : Block Diffusion for Flash Speculative Decoding 什么是 DLLM? 在标准的自回归语言模型中,序列的联合概率分布被严格分解为条件概率的连乘:p(x_1,\dots,x_n)=\prod_{i=1}^n p(x_i\mid x_{<i})直观含义:第 i 个 Token 只能基于它前面的 i-1 个 Token 来预测。 dLLM 抛弃了上述的单向连乘约束,转而借鉴了 Diffusion 模型在图像生成领域的成功经验,定义了一个**加噪与去噪”**的过程: Forward Process (前向加噪):在训练阶段,拿一段干净的...
SD in Llama
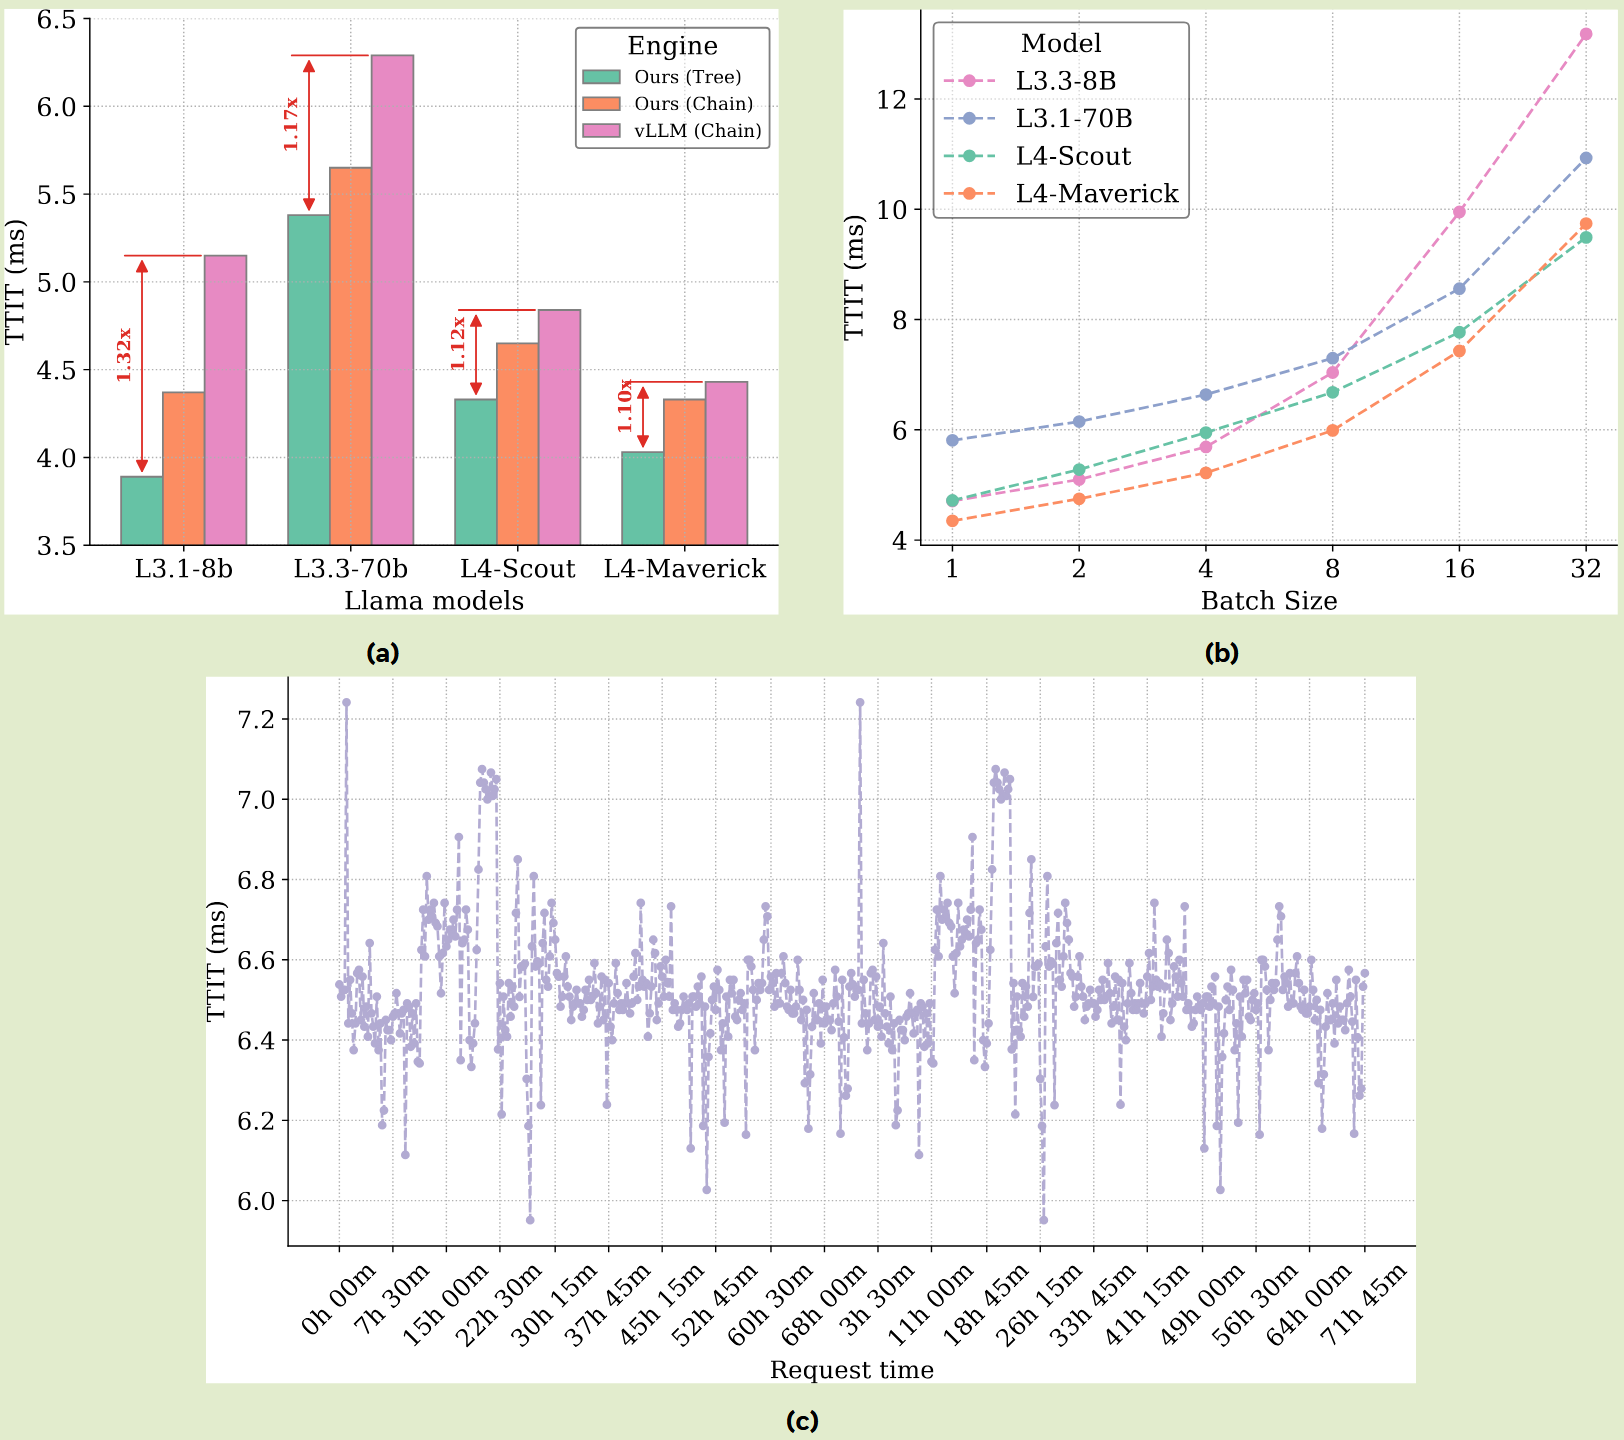
Efficient Speculative Decoding for Llama at Scale: Challenges and Solutions NOTE 在 8 个 NVIDIA H100 GPU 上以每个 token 约 4 ms(批量大小为 1)的速度进行解码,这比之前最知名的方法快了 10%。 对于基于 EAGLE 的推测解码,我们的优化使我们能够在生产规模上实现 1.4 倍到 2.0 倍之间的大规模部署上的加速 这篇文章从训练和推理两方面对现在 eagle-based 的 sd 方法如何在大规模生产环境下使用提出了一些方法。 暂时只看了推理部分 Inference 这里使用了 ...
eagle
(EAGLE 1)EAGLE: Speculative Sampling Requires Rethinking Feature Uncertainty Key Observation 特征(second-to-top-layer)级别的自回归比令牌级别更直接。 这一层的 feature 更有规律,在特征级别进行自回归处理,然后使用原始 LLM 的 LM 头导出标记比直接自回归预测标记更有效率。 采样过程中固有的不确定性极大地限制了预测下一个特征的性能。 对“am”或“always”等不同的 token 进行采样会产生不同的特征序列,从而在特征级自回归中引入歧义 EAGLE 将后一步的 tok...
eagle2
(EAGLE 2)EAGLE-2: Faster Inference of Language Models with Dynamic Draft Trees Key Observation Context-Dependent Acceptance Rates draft token 的接受率与位置相关,位置 P1 的接受率最高,位置 P6 的接受率最低 同一位置的接受率存在显着差异,这表明 draft token被接受的概率不仅取决于其位置,还取决于上下文。这表明上下文感知的动态草图树比静态草图树具有更大的潜力 Well-Calibrated Draft Model 为了应用动态草案树,我们需...
eagle3
(EAGLE 3)EAGLE-3: Scaling up Inference Acceleration of Large Language Models via Training-Time Test Motivation 当前的 EAGLE 范式在 scaling-up 上已经达到了瓶颈,无法通过更多的训练数据来提升 EAGLE 的性能,需要分析原因并改进 Key Observation EAGLE 在特征层面进行自回归预测,预测下一个特征,然后将特征输入到目标模型的 LM head 中以获得 token 分布。 EAGLE 的损失函数由两个部分组成:特征预测损失 l_{fea} 和 toke...
survey on parallel text gen
A Survey on Parallel Text Generation: From Parallel Decoding to Diffusion Language Models AR-Based 遵循 Draft-and-Verify 范式 [图片] 最大目标是最大化期望的吞吐率 A 是 accept tokens L(\mathcal{M})denote the latency of a single forward pass for model M.
batch-invariant kernel
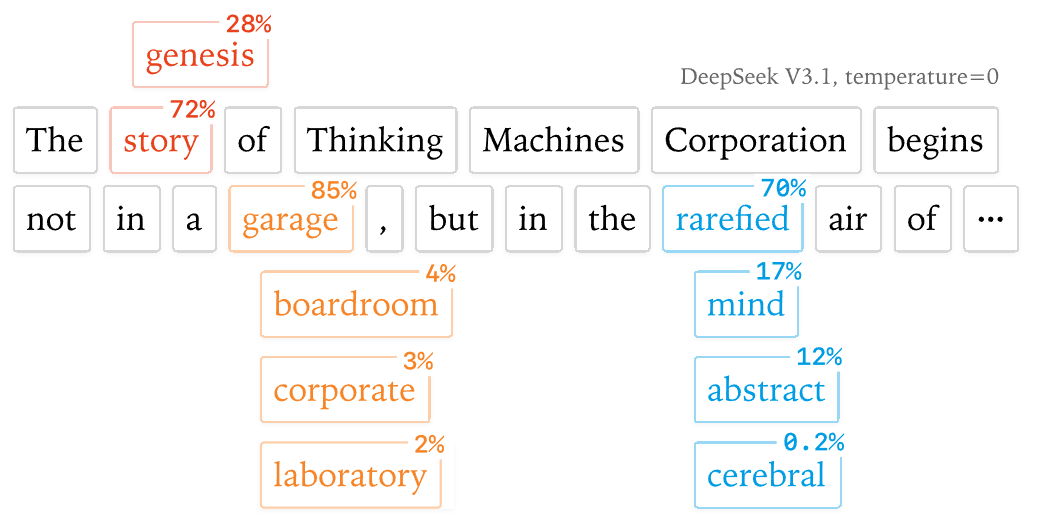
Batch-Invariant Kernel 实际上是在硬件、软件栈以及 sampling temperature = 0 严格受控情况下的,输出确定性 Motivation 浮点结合律 浮点数加法不满足结合律,即:(a + b) + c \neq a + (b + c) 在 GPU 计算中,为了追求极致速度,成千上万个线程会并行计算。如果计算的顺序发生了哪怕一丁点改变,由于舍入误差(Rounding errors),最终的结果在比特位级别(Bit-level)就会产生微小差异。由于 LLM 是一个深度堆叠的非线性系统,这种微小的差异会随着层数增加被迅速放大,最终导致生成的下一个 Token ...
Are You Sure You Want to Use MMAP in Your Database Management System
Are You Sure You Want to Use MMAP in Your Database Management System 论文阅读笔记 Abstract mmap = 💩 永远不要在 DBMS 中应用 mmap Intro 总体介绍 mmap work flow 用户用 mmap 请求读写 cidr.db 文件 mmap 系统调用将其映射到进程的虚拟内存空间中与文件关联,注意此时并没有将文件加载到真实物理内存 直到用户开始访问该文件数据,OS 发现虚拟内存没有对应的物理内存,触发 page fault,此时 OS 将文件的相应部分加载到物理内存中 同时向维护的页表以及 TLB...
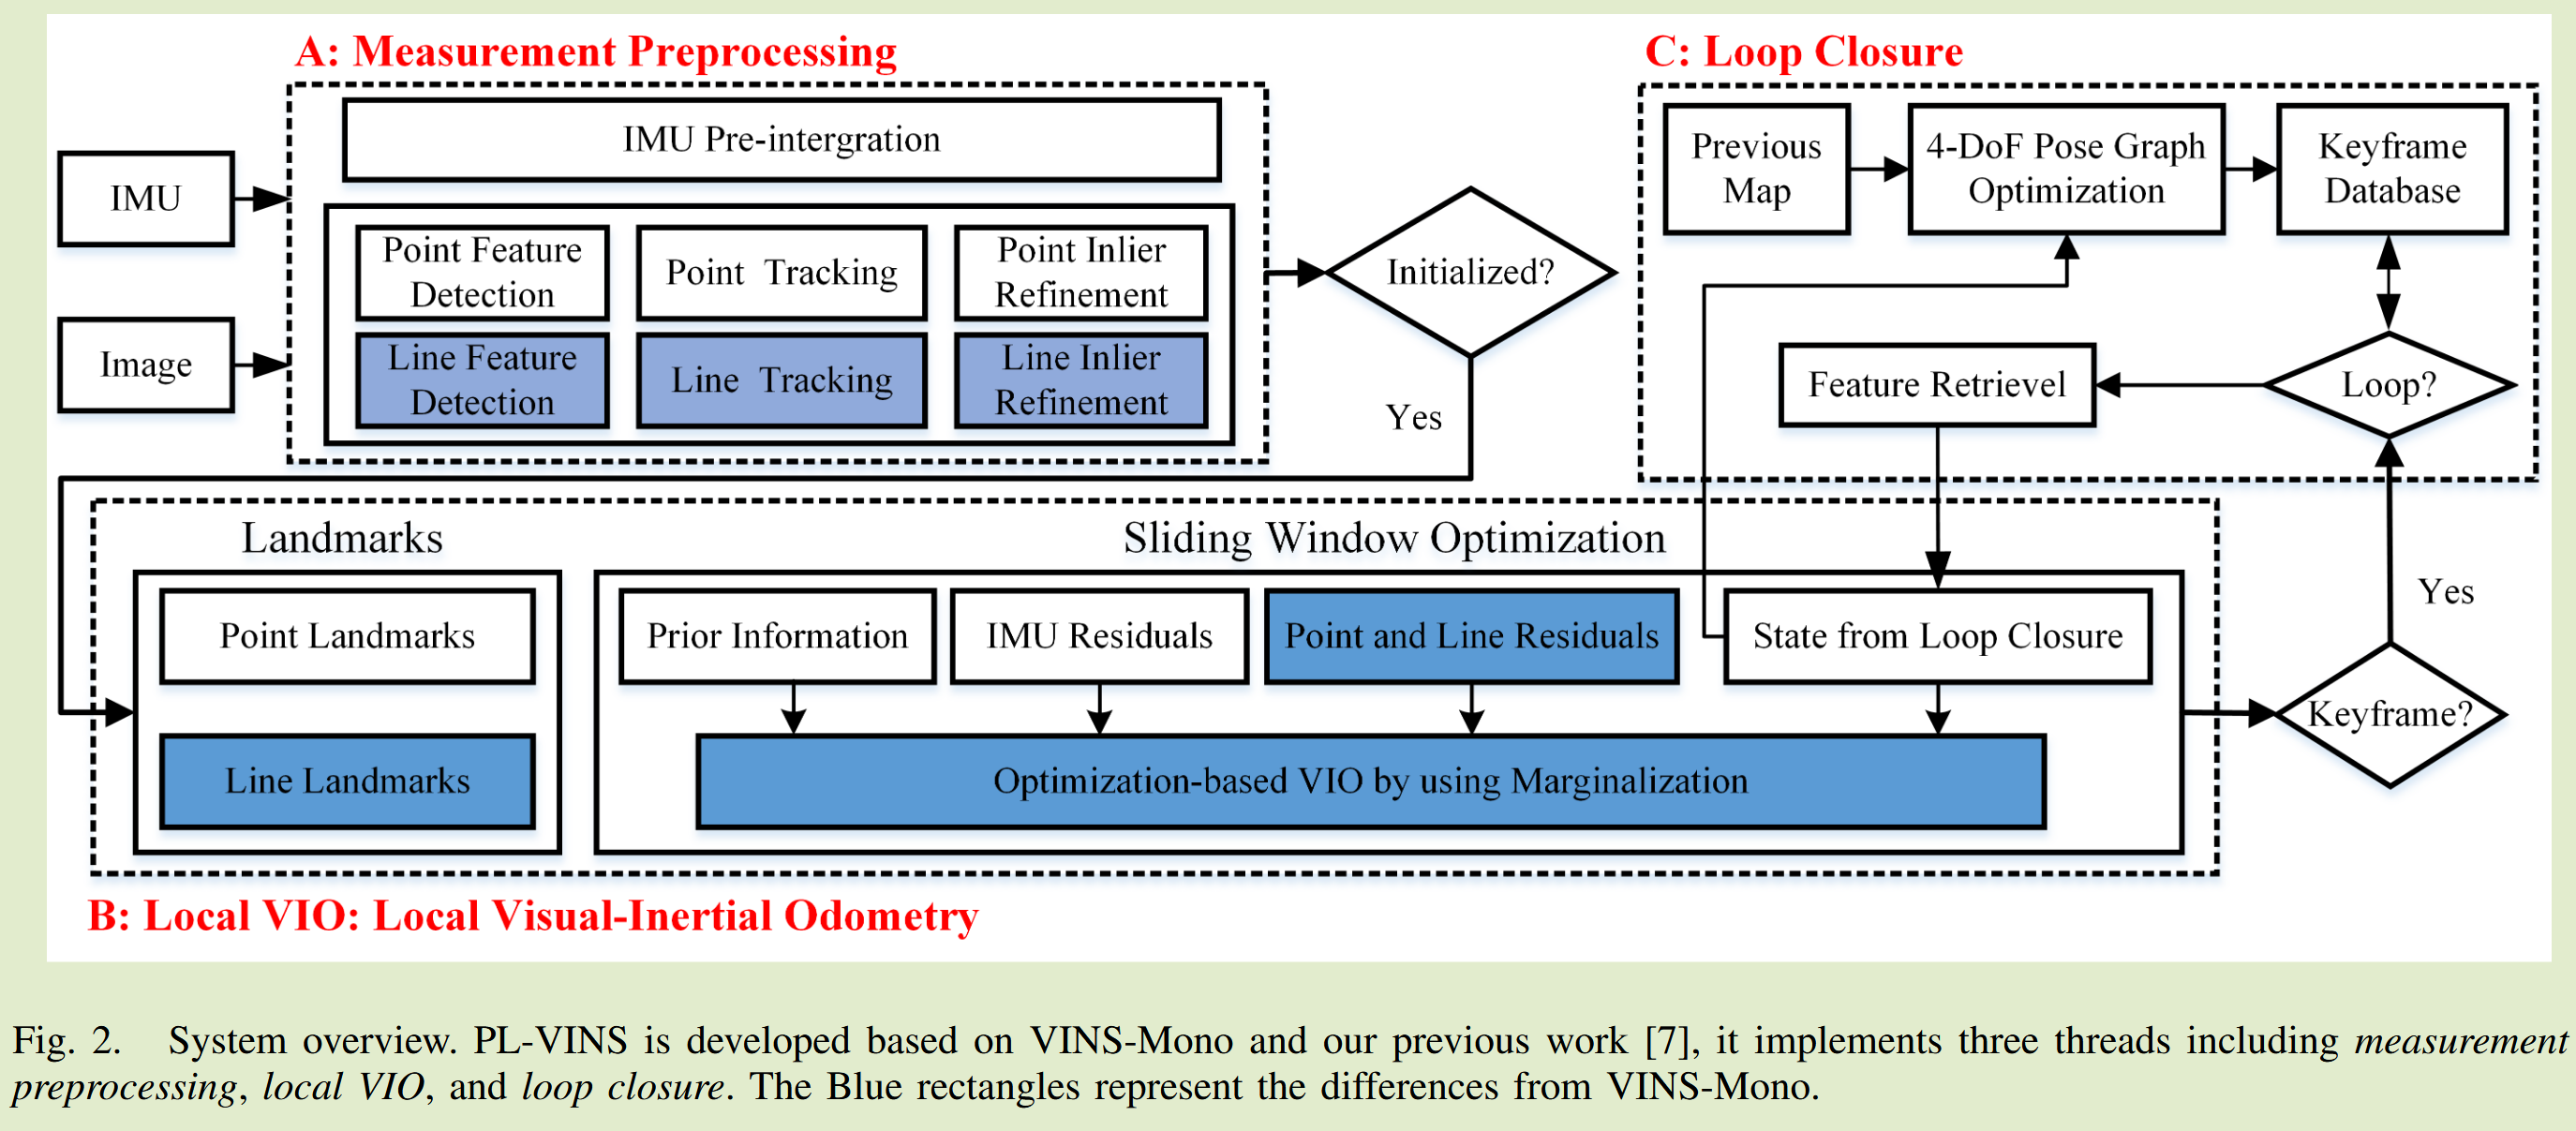
PL-VINS: Real-Time Monocular Visual-Inertial SLAM with Point and Line Features 论文阅读笔记
PL-VINS: Real-Time Monocular Visual-Inertial SLAM with Point and Line Features. PL-VINS is the first real-time optimization-based monocular VINS method with point and line features. A modified LSD algorithm is presented for the pose estimation problem by studying a hidden parameter tuning and length rejection strategy.
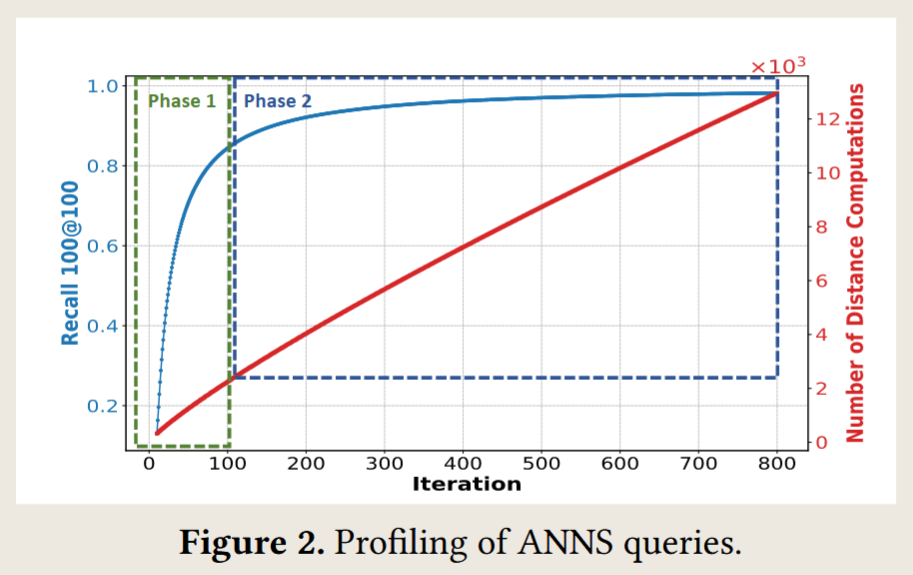
PANNS: Enhancing Graph-based Approximate Nearest Neighbor Search through Recency-aware Construction and Parameterized Search
PANNS: Enhancing Graph-based Approximate Nearest Neighbor Search through Recency-aware Construction and Parameterized Search. It analyzes the graph-based ANNS workload, offers a parameterized search strategy for flexible speed-accuracy trade-offs, and incorporates hidden dimensions through a new proximity graph construction algorithm and graph memory layout optimization.
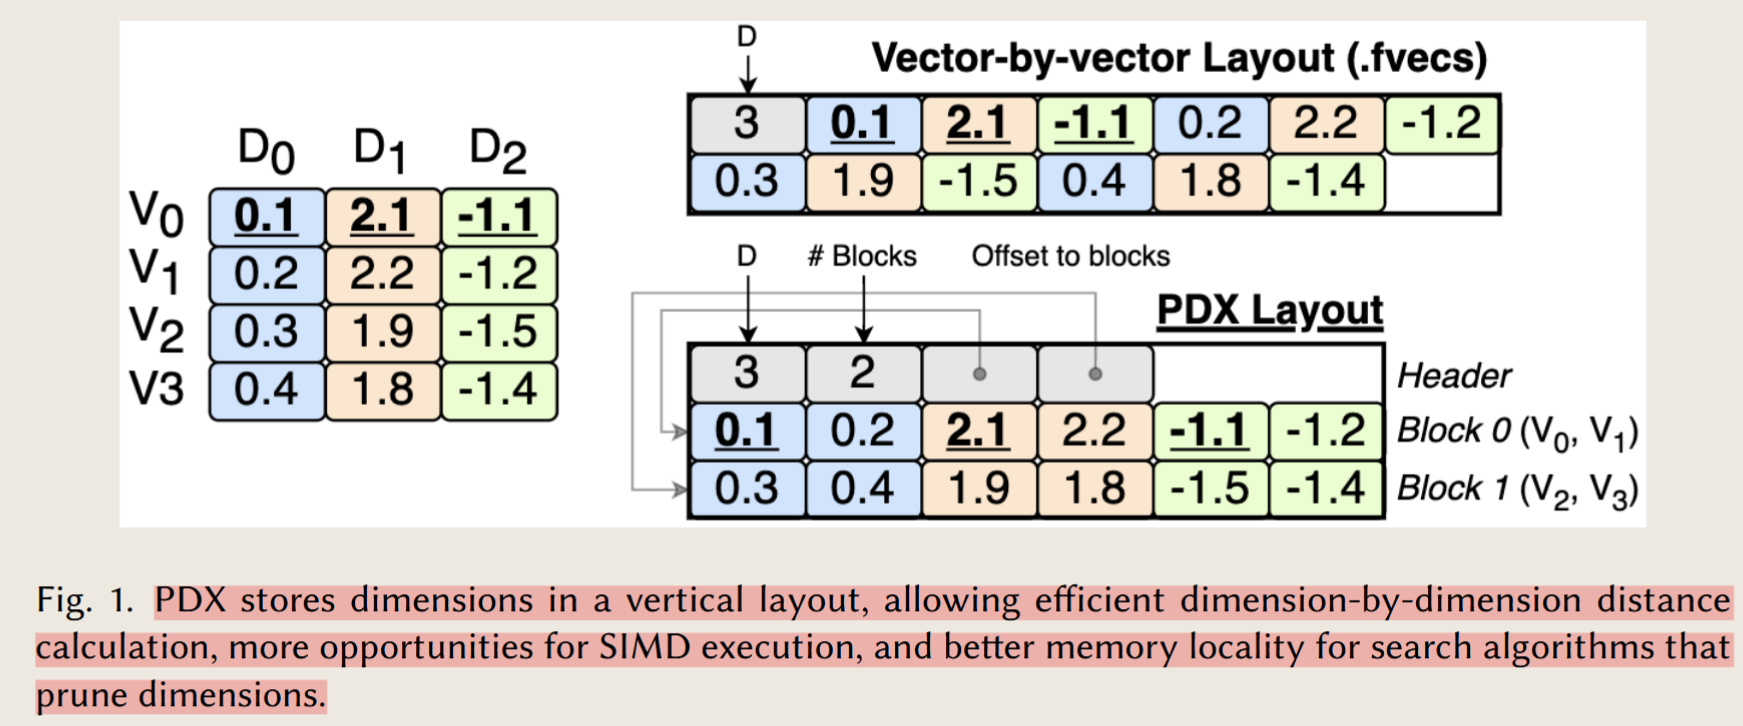
PDX: A Data Layout for Vector Similarity Search
PDX: A Data Layout for Vector Similarity Search. The design of PDX, a new data layout for vectors alongside PDXearch: a framework to perform pruned VSS dimension-by-dimension. The design and evaluation of PDX-BOND leverages the PDX layout to visit first the most relevant dimensions relative to the incoming query. To incorporate hidden dimensions not embedded into vectors, it proposes a new proximity graph construction algorithm and a graph memory layout optimization.
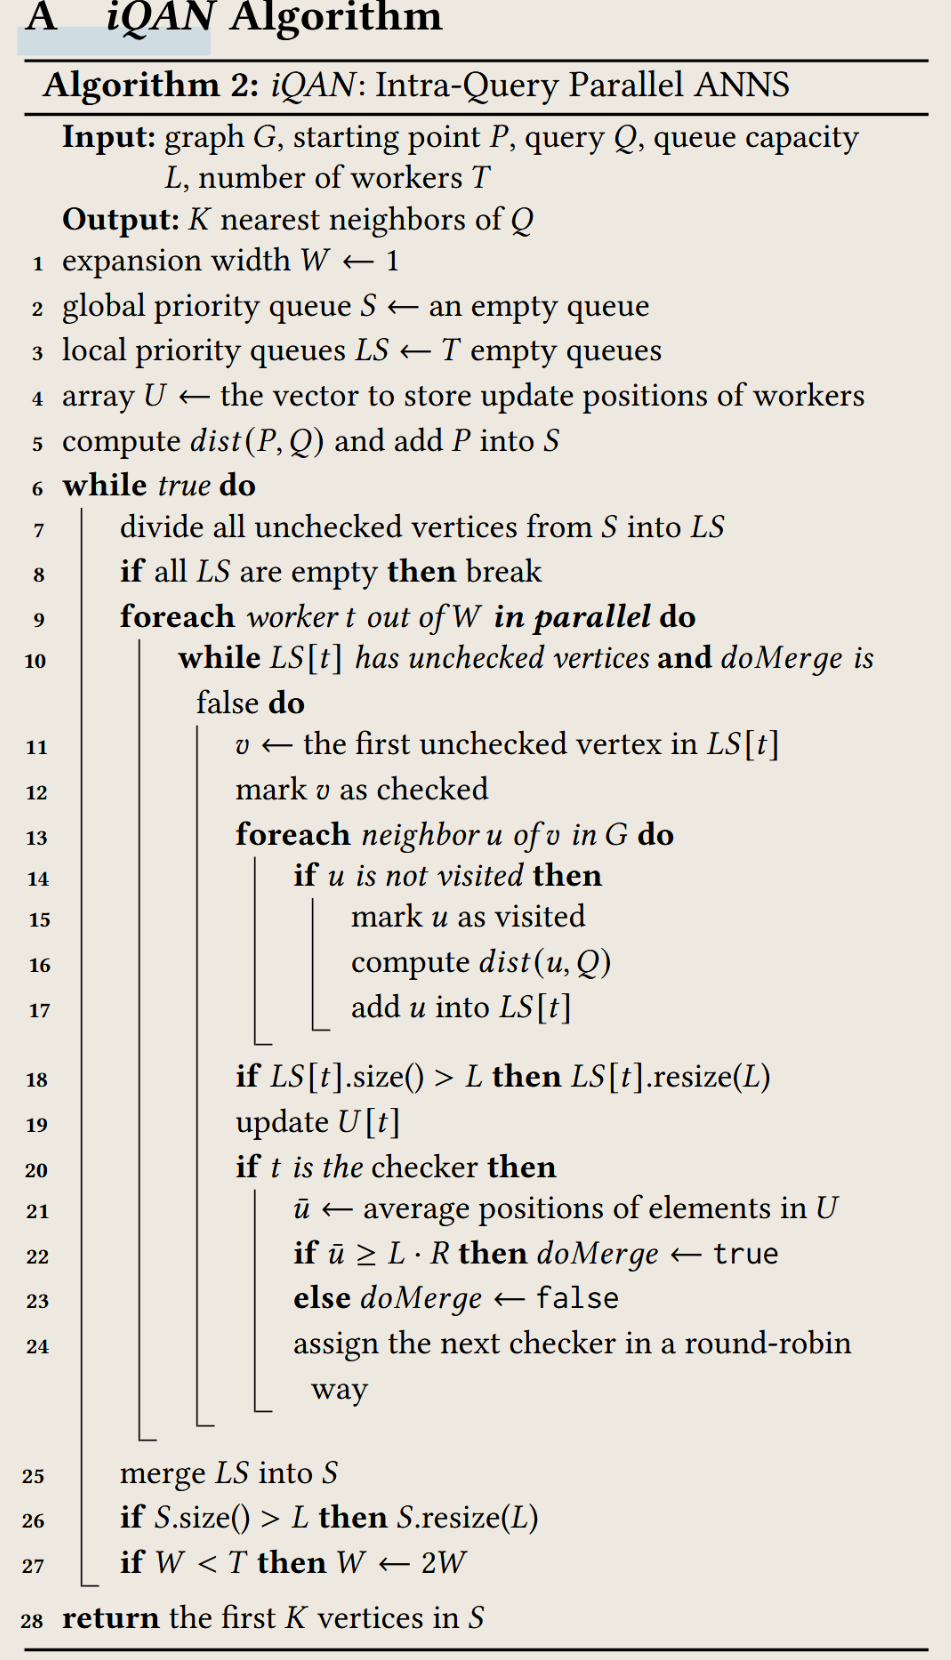
iQAN: Fast and Accurate Vector Search with Efficient Intra-Query Parallelism on Multi-Core Architectures 论文阅读笔记
iQAN: Fast and Accurate Vector Search with Efficient Intra-Query Parallelism on Multi-Core Architectures. It studies the root causes of poor scalability in vector search on multi-core architectures and introduces path-wise parallelism, staged expansion, and redundancy-aware synchronization.
A Large-Scale Disk-Based System for Dynamic Vector Search 论文阅读笔记
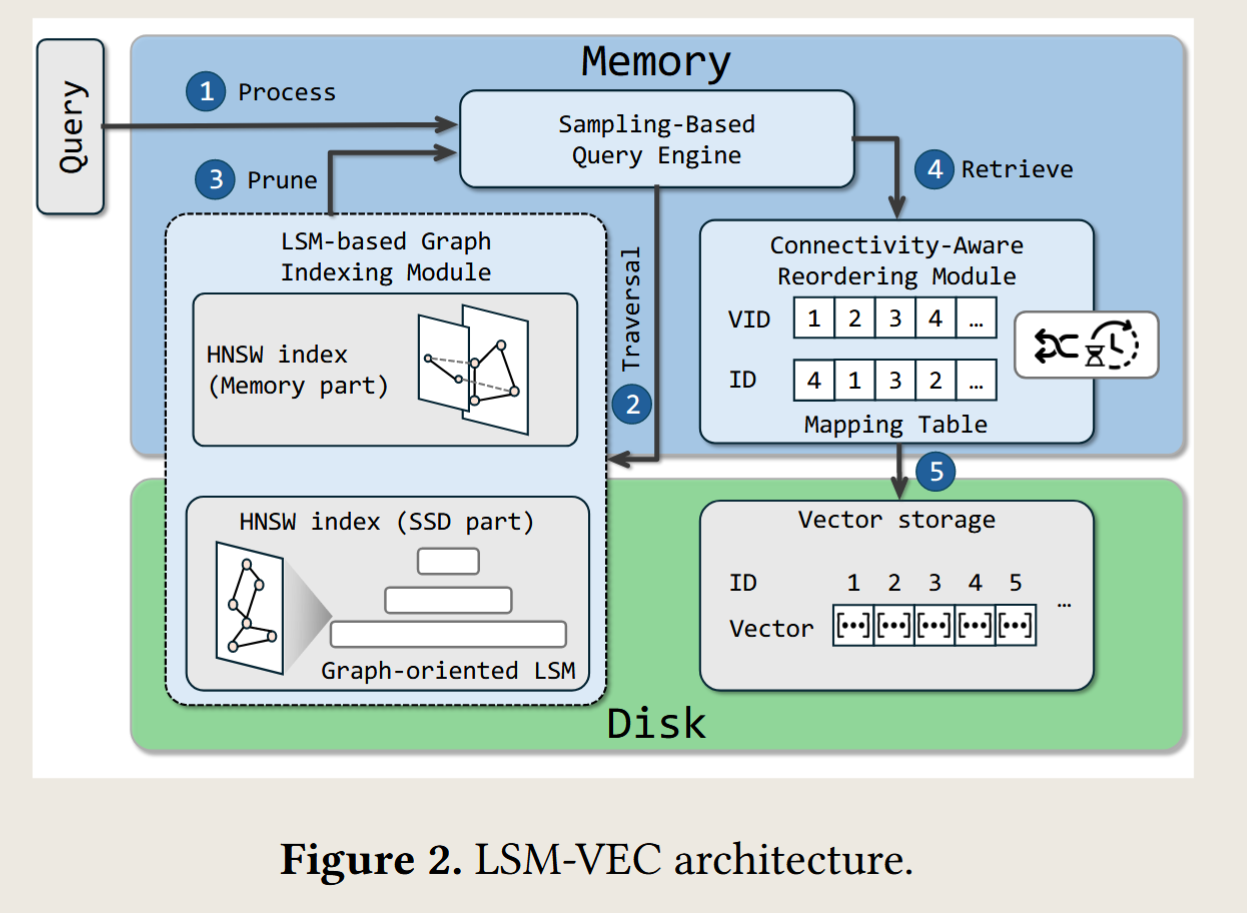
LSM-VEC uses a write-optimized LSM-tree for graph indexes, keeps only the bottom layer on disk, applies locality-aware graph reordering, and uses sampling-guided traversal with probabilistic routing.
MIRAGE-ANNS: Mixed Approach Graph-based Indexing for Approximate Nearest Neighbor Searcha Layout for Vector Similarity Search
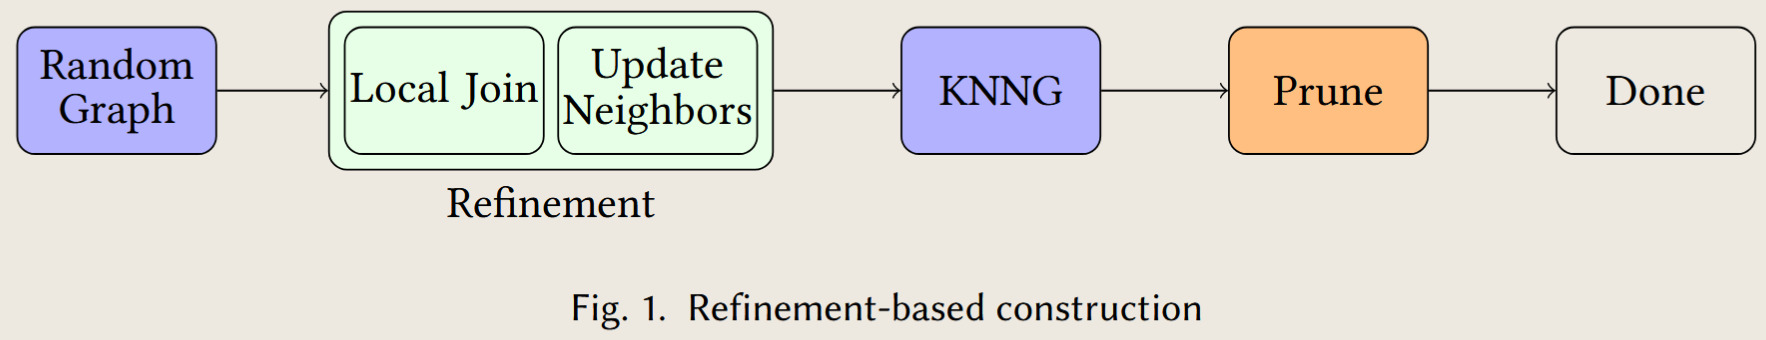
MIRAGE-ANNS: Mixed Approach Graph-based Indexing for Approximate Nearest Neighbor Searcha Layout for Vector Similarity Search. It constructs the index as fast as refinement-based approaches while retaining search performance comparable to or better than increment-based ones.